Odara ETL and dbt
dbt Core turns SQL files into tables and views inside a warehouse or database, with tests and lineage, versioned in Git. It only transforms: moving data between systems, a visual editor and scheduling are left to other tools (or to the paid dbt Cloud).
On the benchmark, dbt with DuckDB had the fastest engine of all six tools. Odara’s case is everything around the SQL: sources and targets, Python, a visual editor, schedules and a Monitor, in one install.
| Odara ETL | dbt Core + DuckDB | |
|---|---|---|
| Licence | Proprietary, free for any use, continuity pledge | Apache 2.0 (dbt Core), MIT (DuckDB), open source |
| Editor | Visual, in the browser; SQL and Python steps | SQL files in your editor; no visual editor |
| Moves data between systems | Yes: databases, warehouses, files, storage, APIs | No: transforms data already in one database |
| Scheduling and monitoring | Included | Not in dbt Core (dbt Cloud is paid, or Airflow, cron…) |
| Needs | Nothing (no JVM) | Python |
Measured, not claimed
We built the same pipeline in both tools and ran it five times on the same machine: read 5,000,000 orders and 200,000 customers from CSV, keep the paid orders, look up each customer’s country, group by country and month (count and sum of the amount), sort, and write the 144 result rows to CSV. Both gave identical results.
Odara ETL 0.4.4
2.0 s median of 5 runs
- Measured
- Run on a running Odara server, through the API (server start: 2.3 s, not included)
- Memory
- 0.44 GB (whole server process)
- Download
- 139 MB
- Needs
- Nothing (no JVM)
- Licence
- Proprietary, free for any use, continuity pledge
dbt Core + DuckDB dbt-core 1.12.7, dbt-duckdb 1.11.1, DuckDB 2.0.0
3.0 s median of 5 runs
- Measured
- dbt run, end to end; includes about 2 s of dbt start-up (the query itself: about 0.6 s)
- Memory
- 0.46 GB
- Download
- 391 MB (Python virtual environment)
- Needs
- Python
- Licence
- Apache 2.0 (dbt) and MIT (DuckDB), open source
- DuckDB’s engine is the fastest in this test: the query takes about 0.6 s, against about 2 s for Odara’s run.
- dbt only transforms: no connectors to move data between systems, no visual editor, and no scheduler in dbt Core (dbt Cloud is paid).
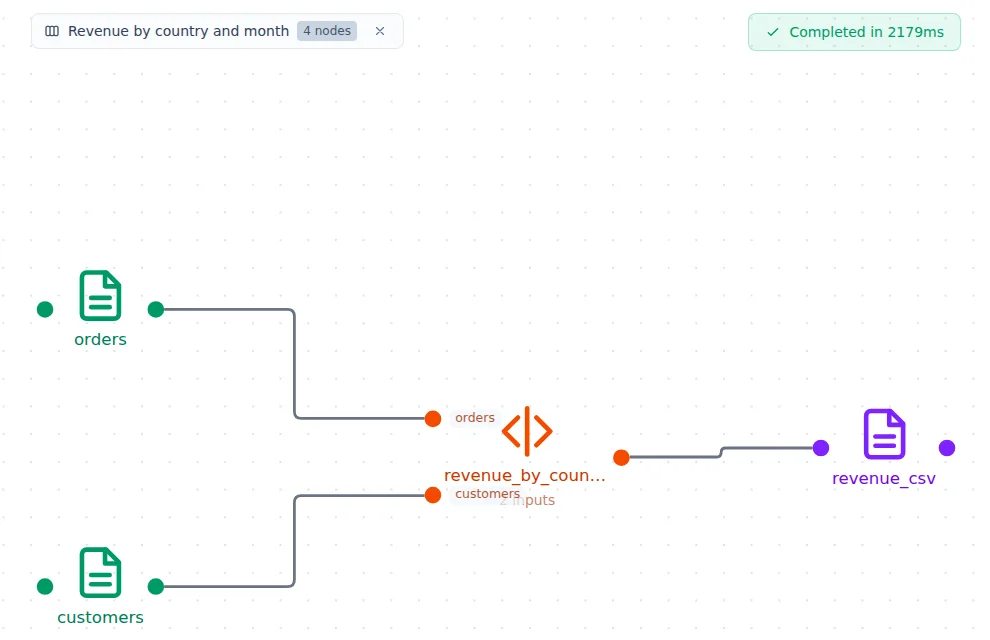
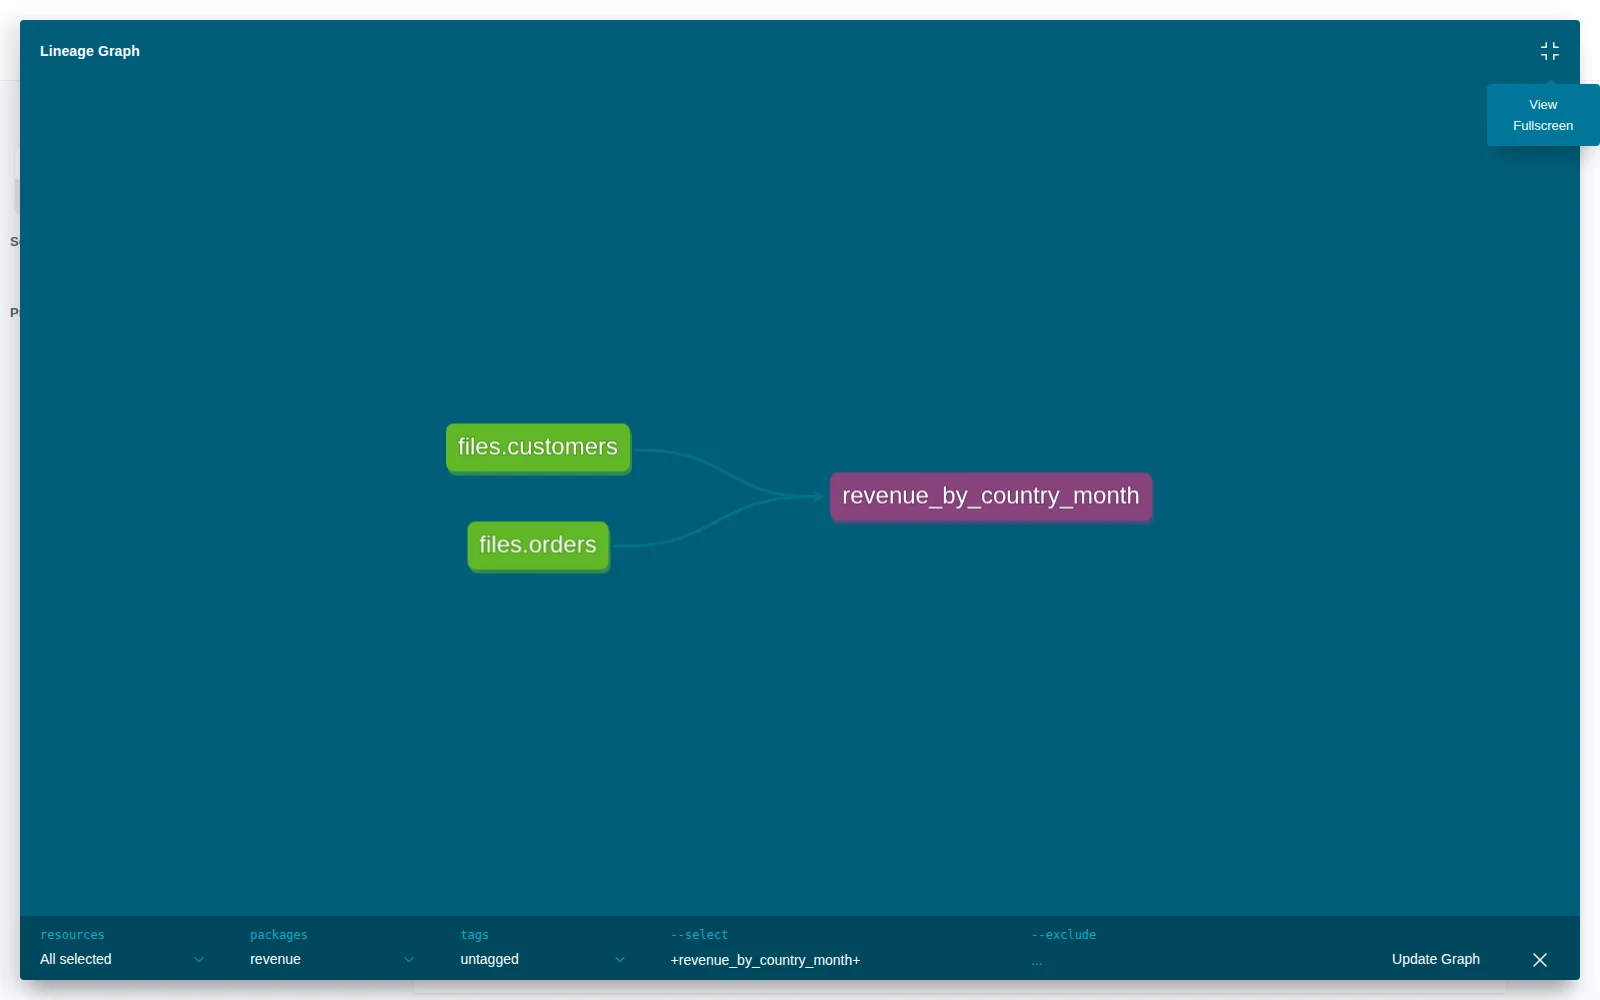
Method, all six tools tested and the files to repeat it yourself: the benchmark.
Choose dbt Core + DuckDB if
- your data is already in one warehouse or database and your team works in SQL and Git
Choose Odara ETL if
- data has to move between systems, not only be transformed in one
- part of your team prefers a visual editor to SQL files
- you want schedules and a run Monitor without another tool
Other comparisons: KNIME Analytics Platform, Apache NiFi, Apache Hop, Talend Open Studio. All six tools: the benchmark.