Odara ETL and Apache NiFi
Apache NiFi is an open-source server for moving data continuously between systems: routing, back-pressure, guaranteed delivery and a record of where each piece of data went. Odara is built for batch pipelines: read, join, transform, aggregate and load.
They solve different problems, so the benchmark below is a batch pipeline, which is Odara’s ground. On continuous ingestion NiFi is the stronger tool.
| Odara ETL | Apache NiFi | |
|---|---|---|
| Licence | Proprietary, free for any use, continuity pledge | Apache 2.0, open source |
| Built for | Batch ETL/ELT pipelines and orchestration | Continuous data flows and routing |
| Transforms | SQL (DataFusion) and Python steps, Mapper | Record processors (QueryRecord SQL, LookupRecord, scripts) |
| Runtime | One native binary | Java 21 server, about 16 s to start |
| Download | 139 MB | 847 MB, plus Java |
Measured, not claimed
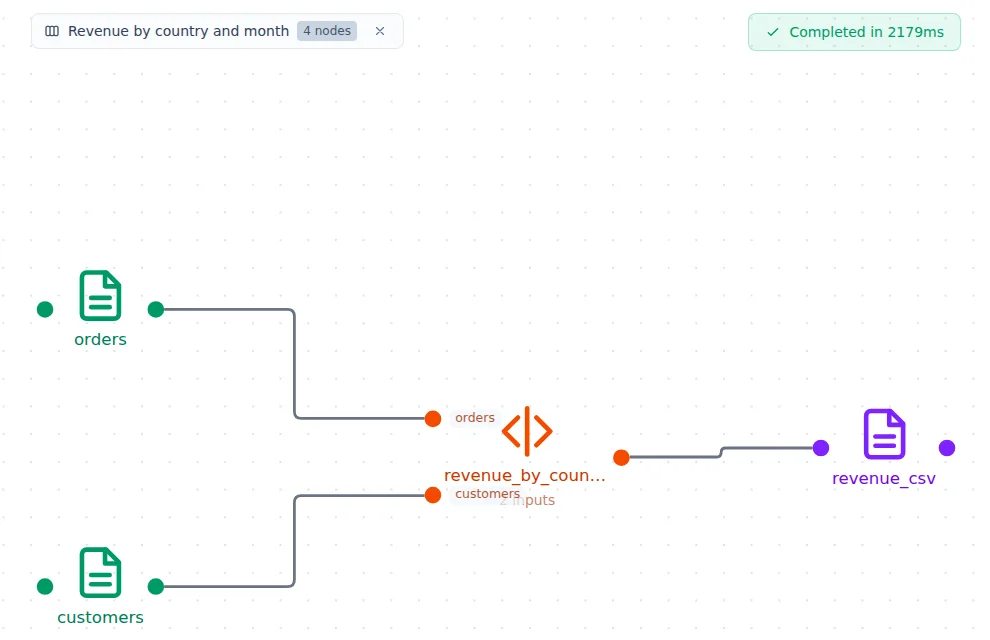
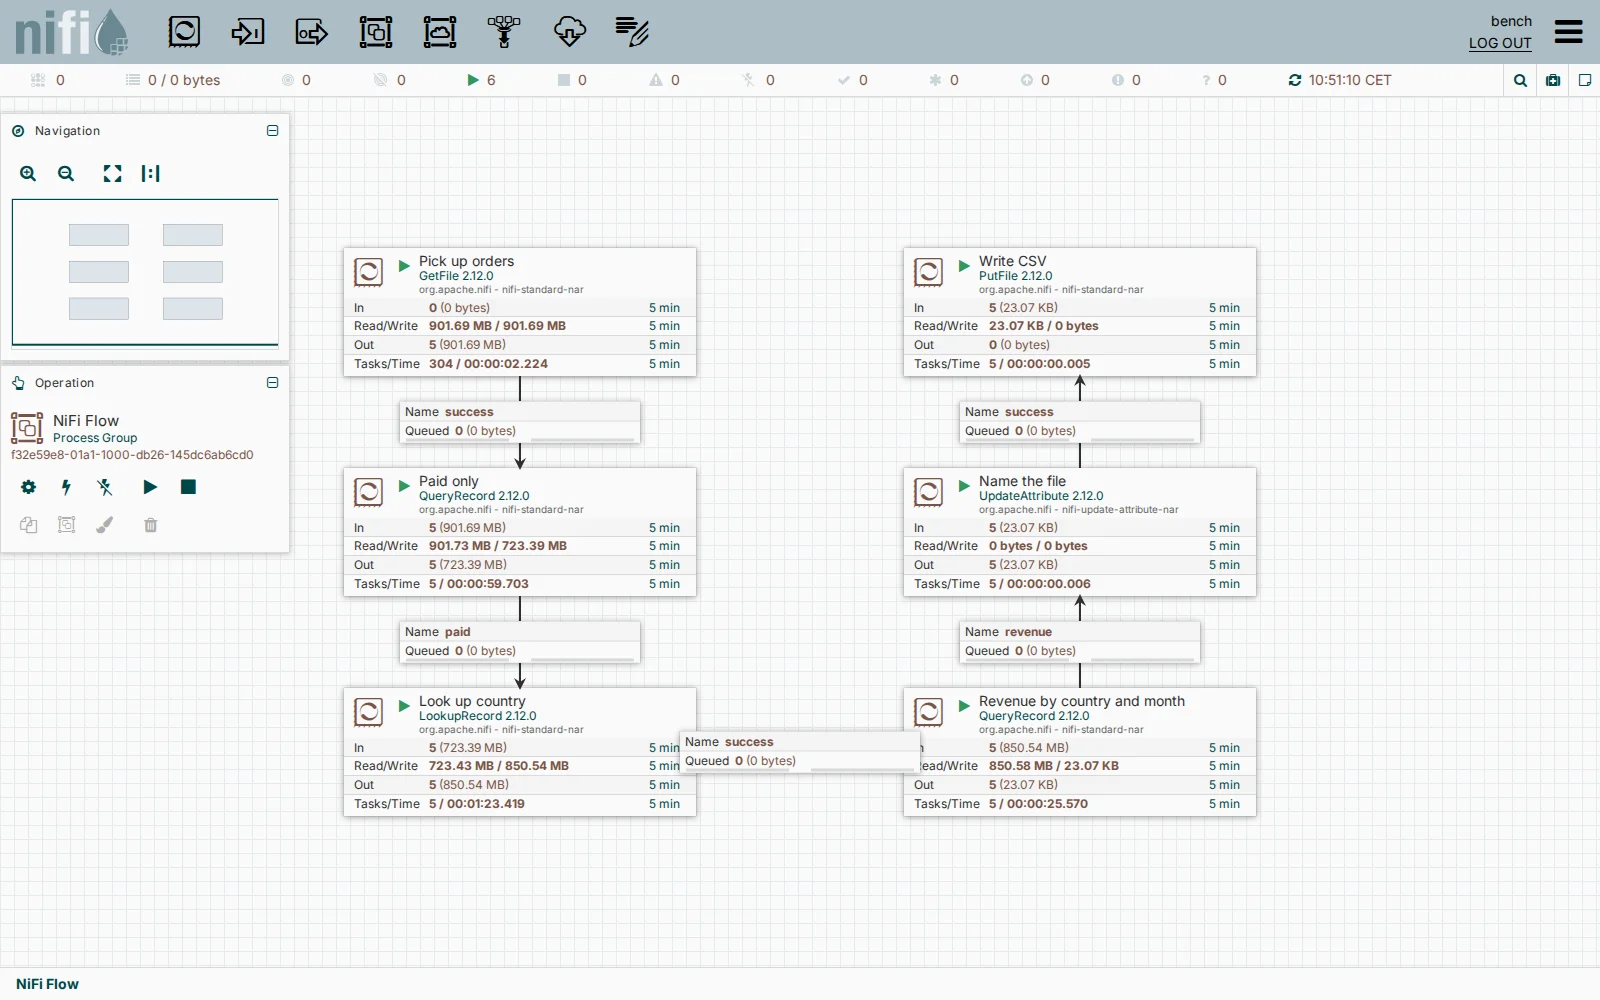
We built the same pipeline in both tools and ran it five times on the same machine: read 5,000,000 orders and 200,000 customers from CSV, keep the paid orders, look up each customer’s country, group by country and month (count and sum of the amount), sort, and write the 144 result rows to CSV. Both gave identical results.
Odara ETL 0.4.4
2.0 s median of 5 runs
- Measured
- Run on a running Odara server, through the API (server start: 2.3 s, not included)
- Memory
- 0.44 GB (whole server process)
- Download
- 139 MB
- Needs
- Nothing (no JVM)
- Licence
- Proprietary, free for any use, continuity pledge
Apache NiFi 2.12.0
35.5 s median of 5 runs
- Measured
- Flow already running on a NiFi server, from the file landing to the result written (server start: 16 s)
- Memory
- 1.66 GB (server, default 1 GB heap)
- Download
- 847 MB, plus a Java runtime
- Needs
- Java 21
- Licence
- Apache 2.0, open source
- NiFi moves and routes data continuously; a batch join and aggregation is not what it is built for. Each step reads and writes the whole file again.
- Default settings, no parallel tasks or file splitting.
Method, all six tools tested and the files to repeat it yourself: the benchmark.
Choose Apache NiFi if
- you move data continuously from many sources and need back-pressure, guaranteed delivery and a record of where every record went
Choose Odara ETL if
- your work is batch: nightly loads, joins, aggregations, files and databases
- you want SQL and Python in the same pipeline
- you want a light server: 0.44 GB against 1.66 GB in this test
Other comparisons: KNIME Analytics Platform, dbt Core + DuckDB, Apache Hop, Talend Open Studio. All six tools: the benchmark.